When One Server Is Not Enough, Put Hundreds to Work Together

Some workloads are too big for any single machine. Simulations, research, AI training, and large-scale analysis need many computers working as one. Datacipher designs, builds, and supports high-performance computing clusters that turn work measured in weeks into work measured in hours, so your teams get answers at the speed the work demands.

Business Challenges

The Work Is Bigger Than Any One Machine
Simulation, modeling, research, and AI training reach a scale where a single server simply cannot finish the job in a reasonable time.
When a run takes days or weeks, the pace of research or development is set by the computer, not by the people doing the work.
An HPC cluster is not just more servers. It needs the right interconnect, storage, and scheduling designed together, which is specialist work most teams have never had to do.
Without proper scheduling, expensive compute either sits idle or becomes a bottleneck that teams queue behind, and both waste the investment.
Demand for GPU-heavy AI training and large-scale data analysis is rising fast, and infrastructure built for ordinary workloads cannot keep up.

Our Solution

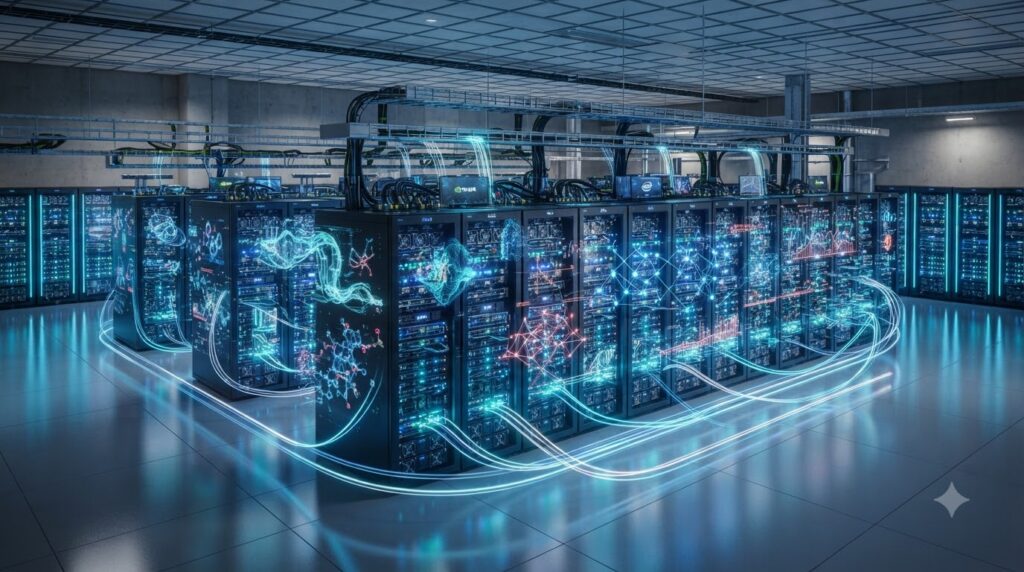
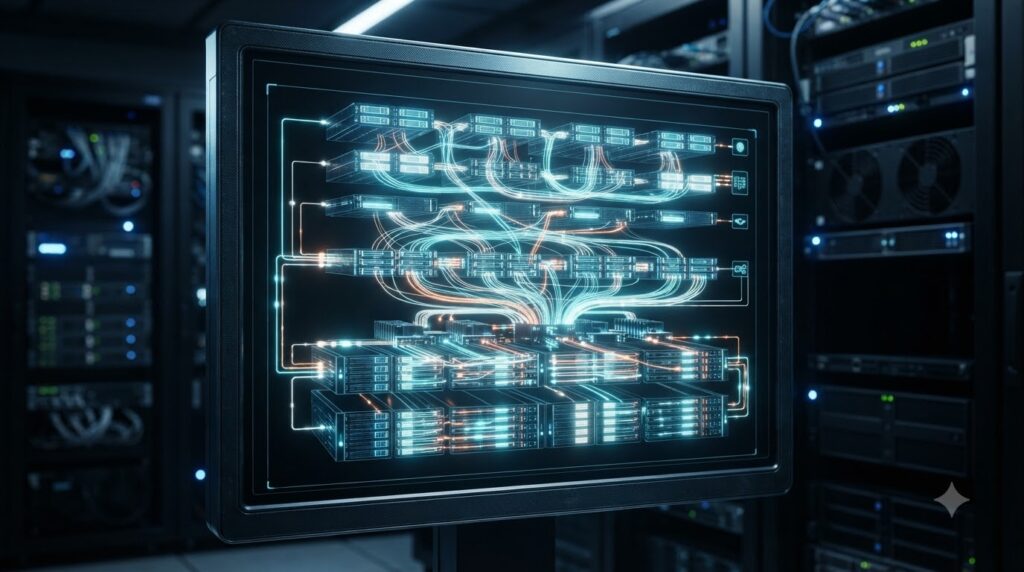
Datacipher designs, builds, and supports high-performance computing clusters built for the work you actually run, whether that is scientific and engineering simulation, research, large-scale analytics, or AI and machine learning training. An HPC cluster is many compute nodes working together as one system, and getting it right means designing the compute, the high-speed interconnect, the storage, and the scheduling to work as a whole.

We start from your workloads and what is slowing them down, then design a cluster from leading OEM hardware, with GPU acceleration where the work calls for it. We build it, set up the scheduling so the cluster stays busy and jobs run in the right order, and support it afterward. The result is infrastructure that matches the scale of the problem, so your teams stop waiting on the computer.

Key Features

Cluster Designed Around Your Workload

Compute, interconnect, storage, and scheduling designed together for the specific work you run, rather than assembled from generic parts.

High Speed, Low Latency Interconnect

The fast network that lets nodes work together as one, so large parallel jobs are not held back by how quickly the nodes can communicate.

GPU Acceleration

GPU-heavy configurations for AI training, machine learning, and other workloads that run far faster on accelerated hardware.

Parallel Storage Built for Throughput

Storage designed to feed data to many nodes at once, so the cluster is not left waiting on data it cannot read fast enough.

Workload Scheduling

A scheduler that shares the cluster across teams and jobs, so expensive capacity stays busy, and work runs in a sensible order.

Business Benefits

1

Answers in Hours, Not Weeks

Work spread across many nodes finishes far faster, so research and development move at the pace of the people, not the hardware.

2

Infrastructure That Matches the Problem

A cluster sized and designed for your workloads means the compute is there when the work demands it, rather than falling short.

3

Full Value From Expensive Compute

Proper scheduling keeps costly hardware busy and shared fairly, so the investment is used rather than sitting idle or bottlenecked.

4

Ready for AI and Large Scale Data

GPU-accelerated design meets the rising demand for AI training and heavy analytics, so the infrastructure keeps up as the work grows.

5

Specialist Work, Handled

The difficult parts of building and running a cluster are taken care of, so your teams focus on the work rather than the infrastructure.

Solution Architecture

The cluster is designed as one system, with compute, interconnect, storage, and scheduling built to work together, deployed from leading OEM hardware and supported by Datacipher.

OEM Partners

We design and deploy high-performance computing on leading OEM compute, GPU, interconnect, and storage platforms, selecting and combining the technology that fits your workloads rather than defaulting to a single make.

Image gallery marquee

Proven Customer
Outcomes

Delivering measurable business results through enterprise networking, cybersecurity, and cloud solutions that improve performance, resilience, and operational efficiency.
Case Study

From 20 Hours of Downtime to Under 1 Hour

DDoS attacks were knocking RailTel offline for nearly 20 hours a month. For one of India’s largest telecom providers, that couldn’t continue. Datacipher deployed Corero’s hybrid DDoS protection, phased in with zero disruption. Downtime fell to under an hour, and attacks now get blocked in real time.

Case Study

50% More Capacity, 70% Fewer Complaints

Rising user demand had pushed QTL’s network into constant congestion, dragging down service quality and pushing customer complaints higher every month. Datacipher upgraded the network with Juniper MX Series routers, rolled out in off-peak hours to avoid disruption. It helped lift overall capacity by 50%, and and cutting performance complaints by 70%.

Case Study

80% Fewer Wi-Fi Dropouts

Mahindra & Mahindra’s ageing Wi-Fi couldn’t keep up with a growing number of devices. Staff hit constant dropouts, and productivity slipped. Datacipher moved them to Juniper Mist, an AI-driven wireless network, phased in with minimal downtime. Connectivity issues fell 80%, and speeds rose 30%.

Case Study

A Data Center Move With Zero Downtime

With its lease expiring and its infrastructure past its prime, Technicolor had just six months to move its entire data center without disrupting a global media operation. Datacipher planned and ran the migration in carefully coordinated phases, hitting the deadline with zero unplanned downtime and moving Technicolor onto faster, more reliable infrastructure.

Case Study

60% Fewer Incidents, 35% Faster

BESCOM’s branch offices were running on outdated firewalls. They couldn’t handle modern threats or rising traffic, so security gaps and slowdowns crept in. Datacipher replaced them with Juniper SRX1500 firewalls, migrating every policy in phases. Security incidents fell 60%, and performance improved 35% across sites.

Case Study

20% More Revenue From New Services

Kerala Vision Broadband wanted to launch new, competitive services but was boxed in by its existing network. Datacipher upgraded the infrastructure with Juniper MX Series routers, adding support for advanced offerings like MPLS-based VPNs. The ISP piloted the services, rolled them out, and lifted revenue 20% in six months.

Why Datacipher

650+ Projects, Proven at Scale

A track record of enterprise engagements delivered across industries.

We Design the Cluster as One System

Our value is getting the compute, interconnect, storage, and scheduling to work together, which is the hard part that decides whether an HPC cluster actually performs.

Built for AI and Accelerated Workloads

With deep server and GPU expertise, we design clusters for the AI and machine learning workloads that increasingly drive the need for HPC.

Support That Doesn't End at Go-Live

Continued monitoring and support through our dedicated Network Operations Center.

FAQs

How is HPC different from just buying powerful servers?
Powerful servers run individual workloads well, but HPC links many nodes so they work together on a single large job. It takes the right interconnect, storage, and scheduling designed as one system, which is what makes work finish far faster than any single machine could manage.
No. Research and simulation are common uses, but HPC now underpins AI and machine learning training, large scale data analysis, and engineering work across many industries.
It depends on the workload. AI training and certain simulations run far faster on GPUs, while other work does not need them. We design the mix around what you actually run rather than adding accelerators by default.
Through a scheduler that shares the cluster across teams and jobs, so expensive compute stays busy and work runs in a sensible order instead of sitting idle or forming bottlenecks.
No. The compute, GPU, interconnect, and storage are built by leading OEMs. Datacipher designs the cluster, selects and combines the right hardware, builds it, and supports it, which is where the value lies.

Latest from Datacipher

Ready to give your biggest workloads the computing power they need?